

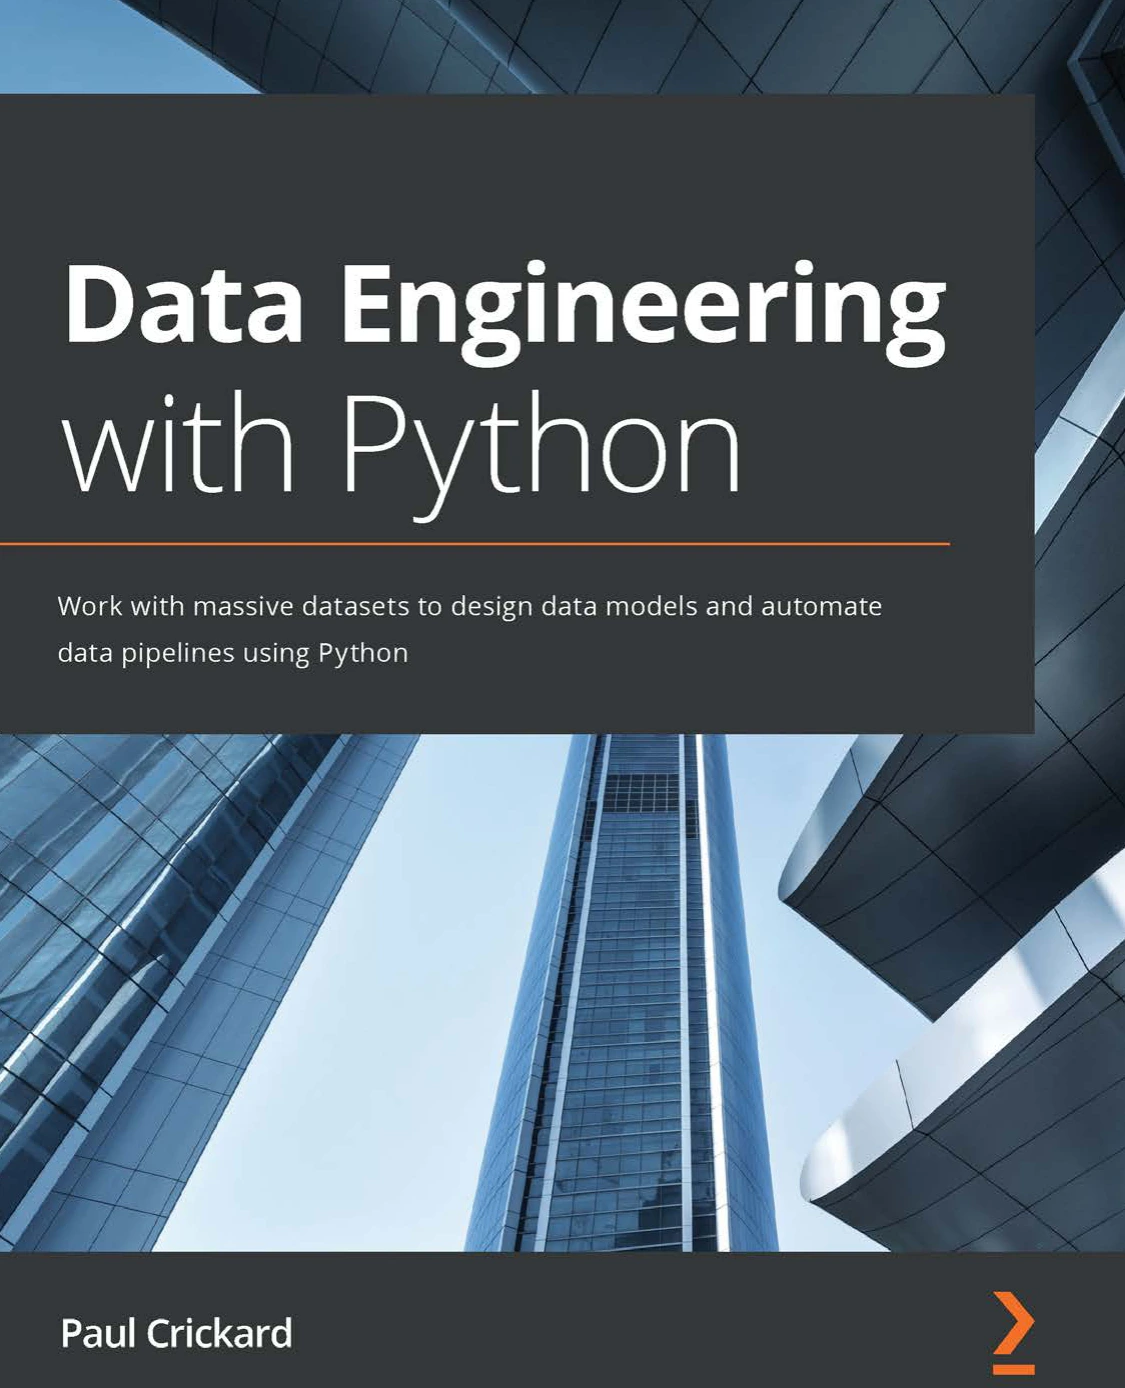
Data Engineering with Python: Work with massive datasets to design data models and automate data pipelines using Python
Original price was: $37.79.$18.89Current price is: $18.89.

Paul Crickard
Product Specs:
- File Type: PDF
- File Size: 10.5 MB
- Book Language: English
- Total Page Count: 357
- Instant Download
Data engineering is where data sources, code, and reliable infrastructure meet. In Data Engineering with Python, Paul Crickard walks through the work of designing data models and assembling automated pipelines, using Python alongside tools such as Apache NiFi, Airflow, PostgreSQL, Elasticsearch, Kafka, and Spark.
The emphasis is practical: follow data as it is read, transformed, stored, monitored, and prepared to run in production. For readers exploring how individual scripts become an organized data workflow, this book offers a structured look at the moving parts.
From data fundamentals to working pipelines
The opening chapters introduce the responsibilities of data engineers, the tools used in the field, and how data engineering supports data science. From there, the book moves into infrastructure and everyday pipeline tasks: handling files, working with relational and NoSQL databases, and preparing data through cleaning, transformation, and enrichment.
Connect Python to the wider data stack
Rather than treating Python as the whole story, the book places it among the services and platforms that help move and manage data. Its examples involve Apache NiFi and Airflow for pipeline work, PostgreSQL and Elasticsearch for data storage and access, and later coverage of Kafka and Spark for streaming and distributed processing.
Think beyond a successful run
A pipeline that works once still has to be made dependable. The production-focused sections address staging and validation, idempotent design, version control, monitoring, logging, and deployment. These topics help frame pipeline development as an operational practice, not simply a sequence of transformations.
A guided, tool-centered approach
The chapter progression moves from core concepts into infrastructure, file and database handling, data preparation, and production workflows. Readers interested in the practical connections between Python code and data engineering systems can use that progression to build context around the components they encounter.
Who may find it useful
This book may be relevant to Python programmers, data practitioners, and learners seeking an introduction to data engineering concepts and pipeline tools. Its examples span several technologies, so some familiarity with programming and working with data will help readers follow the hands-on material.
Explore how the pieces of a data pipeline fit together—and how to plan for the work that begins after the first successful run.
User Reviews
Only logged in customers who have purchased this product may leave a review.
Original price was: $37.79.$18.89Current price is: $18.89.
There are no reviews yet.