

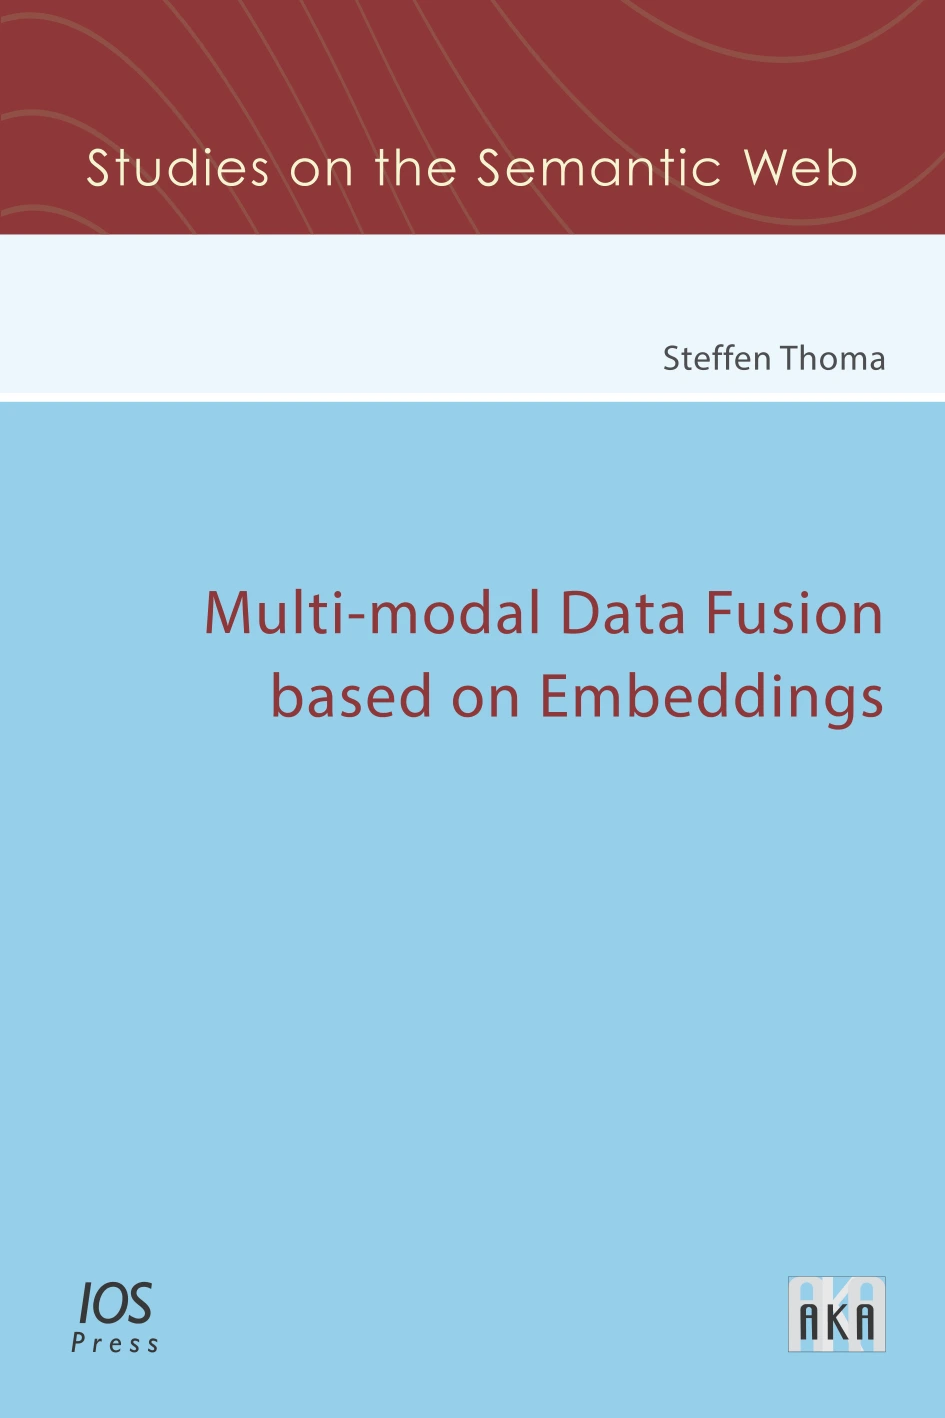
Multi-Modal Data Fusion Based on Embeddings
Original price was: $5.00.$2.50Current price is: $2.50.

Steffen Thoma
Product Specs:
- File Type: PDF
- File Size: 3.1 MB
- Book Language: English
- Total Page Count: 174
- Instant Download
About This Volume
Part of the Studies on the Semantic Web series, this volume collects Steffen Thoma’s doctoral research on making heterogeneous data sources work together. The challenge is familiar to anyone who has tried to combine web data: different providers describe the same entities with different vocabularies, different modelling choices, and varying levels of noise. Thoma’s work asks how embeddings can help machines recognise similar statements across those sources—and then goes further by bringing images and knowledge graphs into the same representation space.
Beyond String Matching: Finding Similarity in Noisy Data
Traditional alignment methods often rely on syntactic string similarity. They struggle with synonyms and cannot easily detect deeper semantic relationships. This research explores the use of RDF label information and textual embeddings to improve integration when data is not clean and perfectly modelled. The experiments reported in the thesis show how semantic similarity measures can outperform purely syntactic approaches in web-scale settings.
Text, Images, and Knowledge Graphs in a Shared Space
Text alone has limits. Many human-obvious facts are never written down, creating a reporting bias that embeddings trained only on language cannot overcome. To address this, Thoma investigates multi-modal learning across three modalities: textual corpora, images, and knowledge graphs. By drawing on computer vision, computational linguistics, and Semantic Web research, the thesis examines whether fusing single-modal representations into a holistic multi-modal representation can capture visual attributes such as shape and colour alongside relational and distributional knowledge.
From Cross-Modal Alignment to Extrapolation
Multi-modal embeddings are powerful, but they depend on cross-modal alignments—connections between concepts in different modalities—that are rare and expensive to create. The final contribution of the thesis develops an extrapolation approach that translates entity representations outside the training corpus into the shared representation space. This helps extend the benefits of multi-modal fusion to concepts that were not part of the original aligned training data.
Who This Research Is For
This is an advanced research monograph based on a 2019 dissertation accepted at the Karlsruher Institut für Technologie (KIT). It will be most valuable to researchers, doctoral students, and practitioners working in Semantic Web technologies, knowledge graph embeddings, data integration, natural language processing, and computer vision. Readers looking for a focused, method-oriented account of embedding-based data fusion will find a clear path from the problem statement through experimental evaluation to the thesis’s final extrapolation method.
A Focused Contribution to Semantic Web Research
If your work involves aligning heterogeneous data, building knowledge graphs, or exploring multi-modal representations, this volume offers a rigorous look at how embeddings can bridge sources that were never designed to fit together. It is part of the Studies on the Semantic Web series, Volume 041.
User Reviews
Only logged in customers who have purchased this product may leave a review.
Original price was: $5.00.$2.50Current price is: $2.50.
There are no reviews yet.