

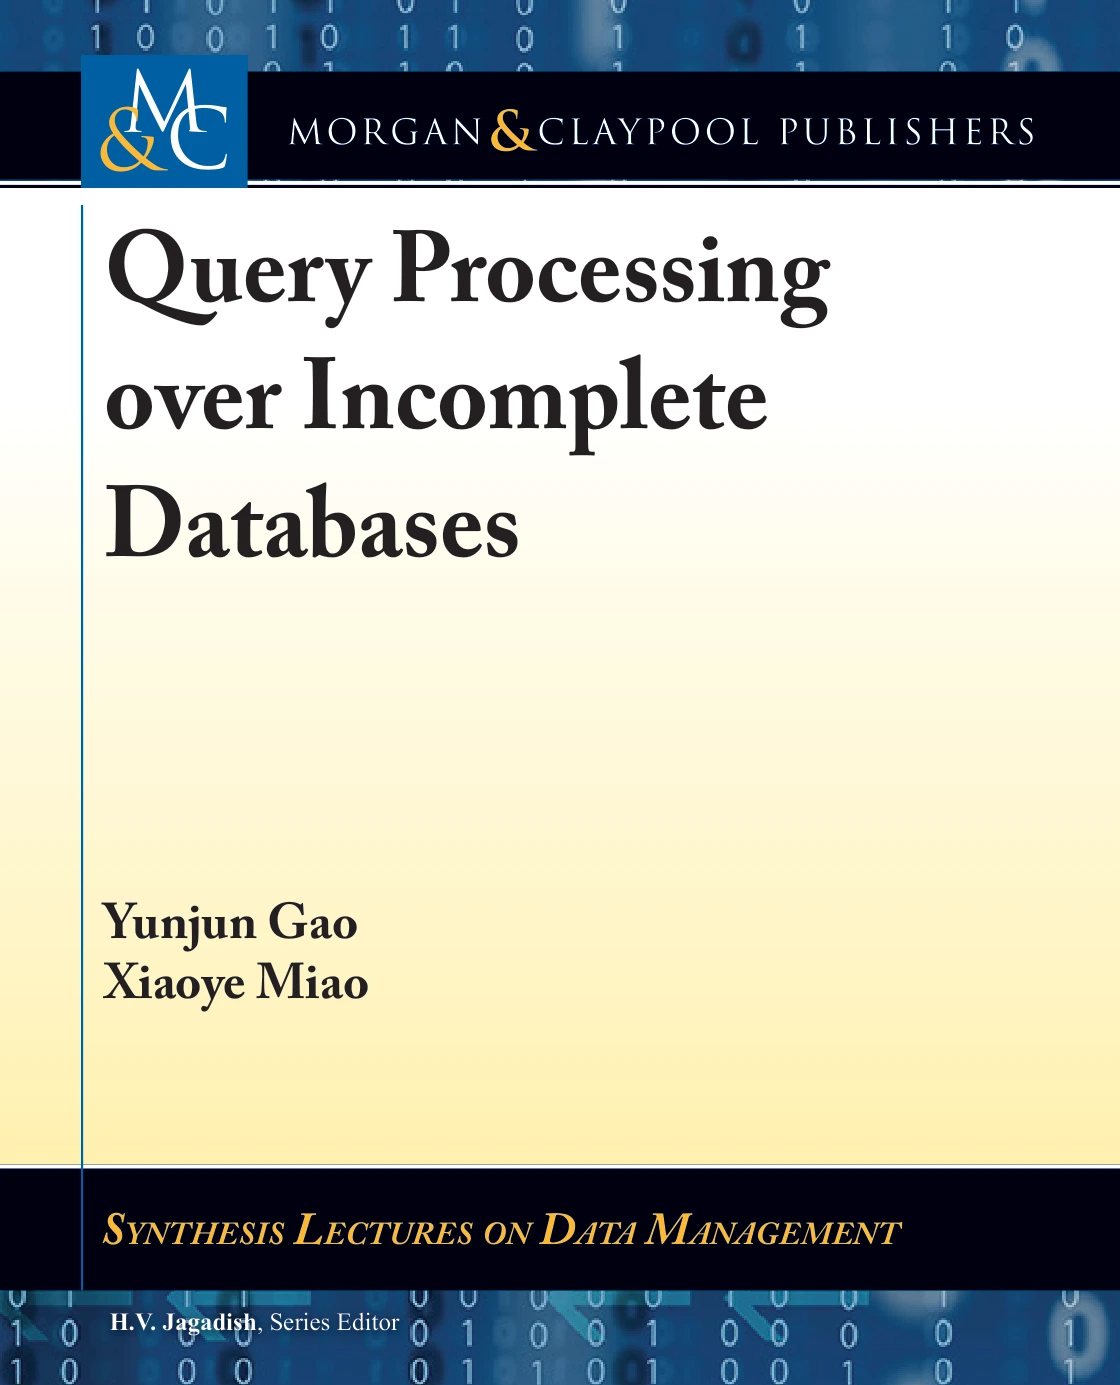
Query Processing over Incomplete Databases
Original price was: $5.00.$2.50Current price is: $2.50.

Yunjun Gao
Product Specs:
- File Type: PDF
- File Size: 1.8 MB
- Book Language: English
- Total Page Count: 124
- Instant Download
When Data Doesn’t Tell the Whole Story
Databases are often expected to be complete and precise, but real-world systems rarely live up to that ideal. Missing values, uncertain attributes, and partial information are common—whether caused by data integration, sensor noise, manual entry errors, or simply the limits of what can be known. Querying such databases is not just a matter of tolerating gaps; it requires a careful reconsideration of what a query even means and how answers should be computed.
Query Processing over Incomplete Databases offers a concise, research-driven exploration of this problem space. Published in 2018 as part of the Synthesis Lectures on Data Management series from Morgan & Claypool, it is written by Yunjun Gao and Xiaoye Miao, two researchers active in the field. The book surveys models and techniques for evaluating queries when the underlying data is incomplete, providing a structured overview that is both accessible and technically grounded.
What the Book Covers
Incomplete information in databases can take many forms: null values, disjunctive constraints, probabilistic tuples, or entire records that are absent. Each representation carries its own semantics and computational challenges. This lecture examines how query processing adapts—or must be adapted—to handle such cases. Rather than focusing on a single system or product, the material draws on established research to explain the core principles that underpin query evaluation under uncertainty and incompleteness.
Because it is part of the Synthesis Lectures series, the book is designed to deliver a focused treatment of the topic rather than an exhaustive handbook. It is ideal for readers who want a clear, reliable entry point into the field and a solid understanding of the fundamental issues before diving into more specialized literature.
Who Will Find It Useful
The book speaks to a range of readers:
- Graduate students and researchers in data management, databases, and related areas who need a rigorous overview of incomplete data querying.
- Practitioners and system architects who encounter incomplete data in production environments and want to understand the theoretical foundations behind practical solutions.
- Anyone curious about the limits of conventional query processing and how the field addresses them.
No prior expertise in incomplete databases is assumed, though a basic familiarity with relational databases and query languages will help readers get the most from the material.
About the Authors
Yunjun Gao and Xiaoye Miao are researchers who have contributed to the study of data management and query processing. Their collaboration on this lecture reflects a shared interest in the challenges that arise when data is imperfect—a topic that remains central to both academic research and industrial practice.
Why This Topic Matters
As data volumes grow and sources multiply, incompleteness becomes the norm rather than the exception. Understanding how queries behave in the presence of missing information is essential for building systems that are robust, trustworthy, and useful. This book provides a thoughtful, well-organized guide to that fundamental problem.
User Reviews
Be the first to review “Query Processing over Incomplete Databases”
You must be logged in to post a review.
Original price was: $5.00.$2.50Current price is: $2.50.
There are no reviews yet.