

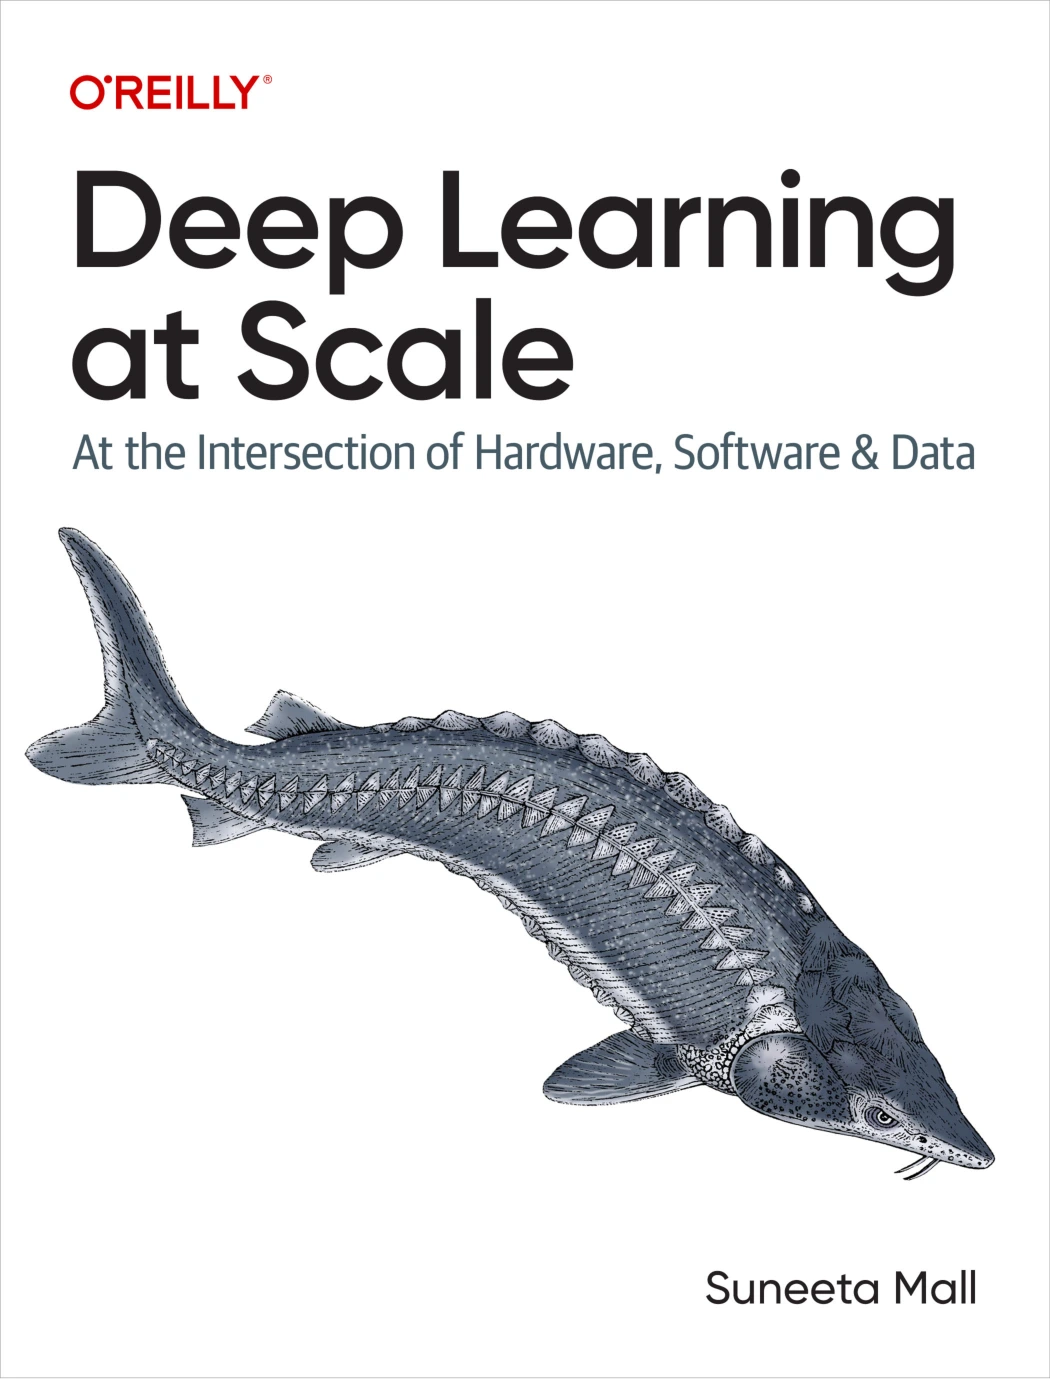
Deep Learning at Scale: At the Intersection of Hardware, Software, and Data
Original price was: $67.99.$33.99Current price is: $33.99.

Suneeta Mall
Product Specs:
- File Type: PDF
- File Size: 20.8 MB
- Book Language: English
- Total Page Count: 448
- Instant Download
Scaling a deep-learning project is not simply a matter of adding more accelerators. Data pipelines, model design, hardware, software, and distributed communication all shape what happens when training grows. In Deep Learning at Scale: At the Intersection of Hardware, Software, and Data, Suneeta Mall connects these moving parts in a technical, hands-on guide for readers working beyond small-scale experiments.
Follow the full deep-learning stack
The book builds from foundational concepts—data flow, computation graphs, model development, and computer architecture—to the practical choices that affect training efficiency. Mall examines accelerated computing, memory and precision considerations, and ways to investigate performance bottlenecks, giving readers a framework for understanding how the pieces of a training workload interact.
From one device to distributed training
As the scope expands, the focus turns to distributed systems and the communication patterns behind distributed deep learning. Dedicated sections cover data parallelism as well as model, pipeline, tensor, and hybrid parallelism. The material also considers infrastructure, dataset pipelines, measurement, and fault-tolerant training—important concerns when a workload must run across multiple devices.
Learn through practical examples
Hands-on exercises thread through the book, with examples involving PyTorch, GPT-2, vision models, DeepFM, and distributed training techniques. Later chapters address data quality, experiment planning, transfer learning, hyperparameter optimization, knowledge distillation, and efficient fine-tuning methods including LoRA and QLoRA. The examples make this a working technical reference rather than a discussion of scaling in the abstract.
For practitioners ready to reason about scale
Designed for intermediate-to-advanced readers, this book is relevant to machine-learning engineers, deep-learning practitioners, and developers who need to make informed choices about training efficiency and distributed workloads. Its central value is the joined-up perspective: scaling decisions are considered across hardware, software, data, and algorithms, rather than as isolated optimizations.
For readers building or evaluating larger deep-learning workflows, Mall’s guide offers a structured path from core concepts to multidimensional training strategies and the challenges of extreme scale. 💻
User Reviews
Only logged in customers who have purchased this product may leave a review.
Original price was: $67.99.$33.99Current price is: $33.99.
There are no reviews yet.