

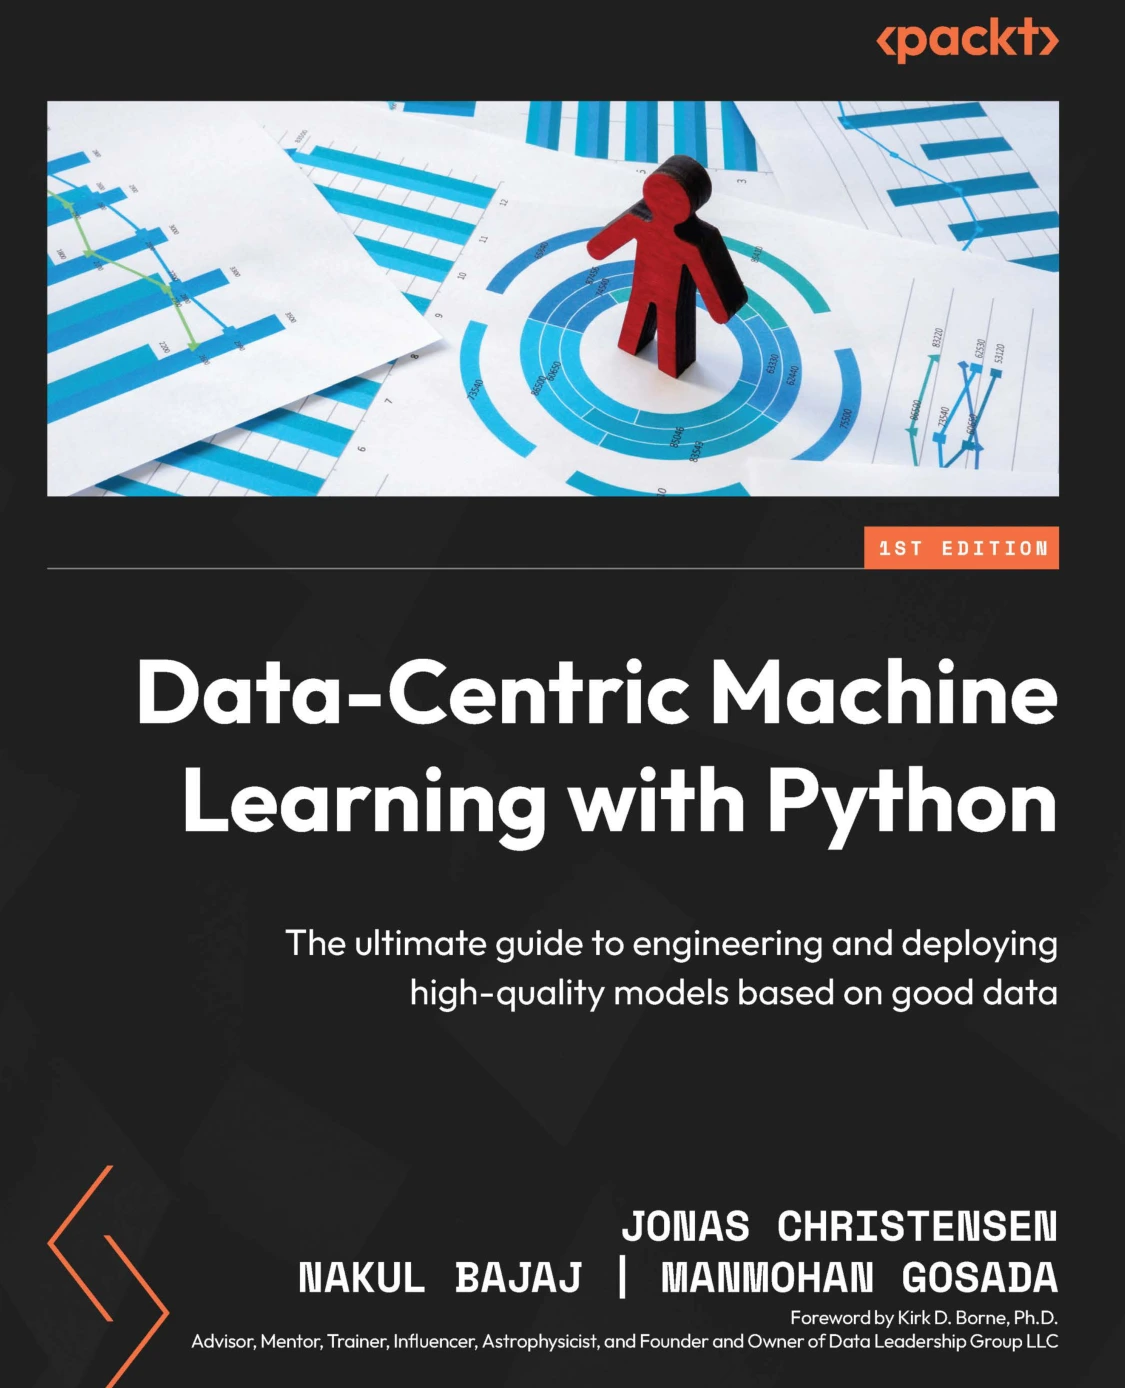
Data-Centric Machine Learning with Python
Original price was: $37.79.$18.89Current price is: $18.89.

Jonas Christensen
Product Specs:
- File Type: PDF
- File Size: 6.0 MB
- Book Language: English
- Total Page Count: 378
- Instant Download
Machine learning discussions often focus on choosing algorithms and improving models. Data-Centric Machine Learning with Python shifts attention to the material those models depend on: the data itself. Jonas Christensen, Nakul Bajaj, and Manmohan Gosada make the case for treating data quality, preparation, and stewardship as core parts of ML development—not as afterthoughts.
Across 16 chapters, the book connects the principles of data-centric machine learning with practical work in Python. Its scope includes data collection and labeling, synthetic data, bias, and the challenges posed by rare events and edge cases. The result is a perspective on building ML systems in which better data work and model development support one another.
Why put data at the center?
The opening chapters define data-centric ML, compare it with model-centric approaches, and explore how the field came to emphasize models. They also examine why data quality matters and how a focus on the data can open opportunities beyond the familiar assumption that more data is always the answer.
This shift is useful for teams deciding where to invest their effort: refining a model is only one part of the work when the data feeding it may be incomplete, inconsistent, biased, or poorly suited to the task.
Practical techniques, grounded in Python
The book moves from its conceptual foundations into the building blocks of data-centric practice. Topics include improving data collection and labels, working with synthetic data, identifying bias, and handling edge cases and rare events. These subjects help readers consider not only how to train a model, but also how the quality and coverage of its data shape its behavior.
Python gives the technical discussion a practical frame, while the book also emphasizes methods and responsibilities that involve the wider team.
Machine learning as a team effort
Good data work is rarely confined to one person or one stage of a project. The authors foreground collaboration, shared responsibility, and the importance of making data a concern across the people who build and use ML systems. Ethical and responsible practice is part of that discussion, rather than a separate consideration added at the end.
Who may find it useful?
This book is relevant to data scientists, machine learning engineers, MLOps practitioners, and technical readers who want to improve the data side of their ML work. Readers looking for a broader view of how data quality, team practices, and Python-based methods fit together will find a clear path from foundational ideas toward applied techniques.
For anyone who has spent more time tuning a model than questioning its data, this book offers a thoughtful reason to look upstream.
User Reviews
Only logged in customers who have purchased this product may leave a review.
Original price was: $37.79.$18.89Current price is: $18.89.
There are no reviews yet.