

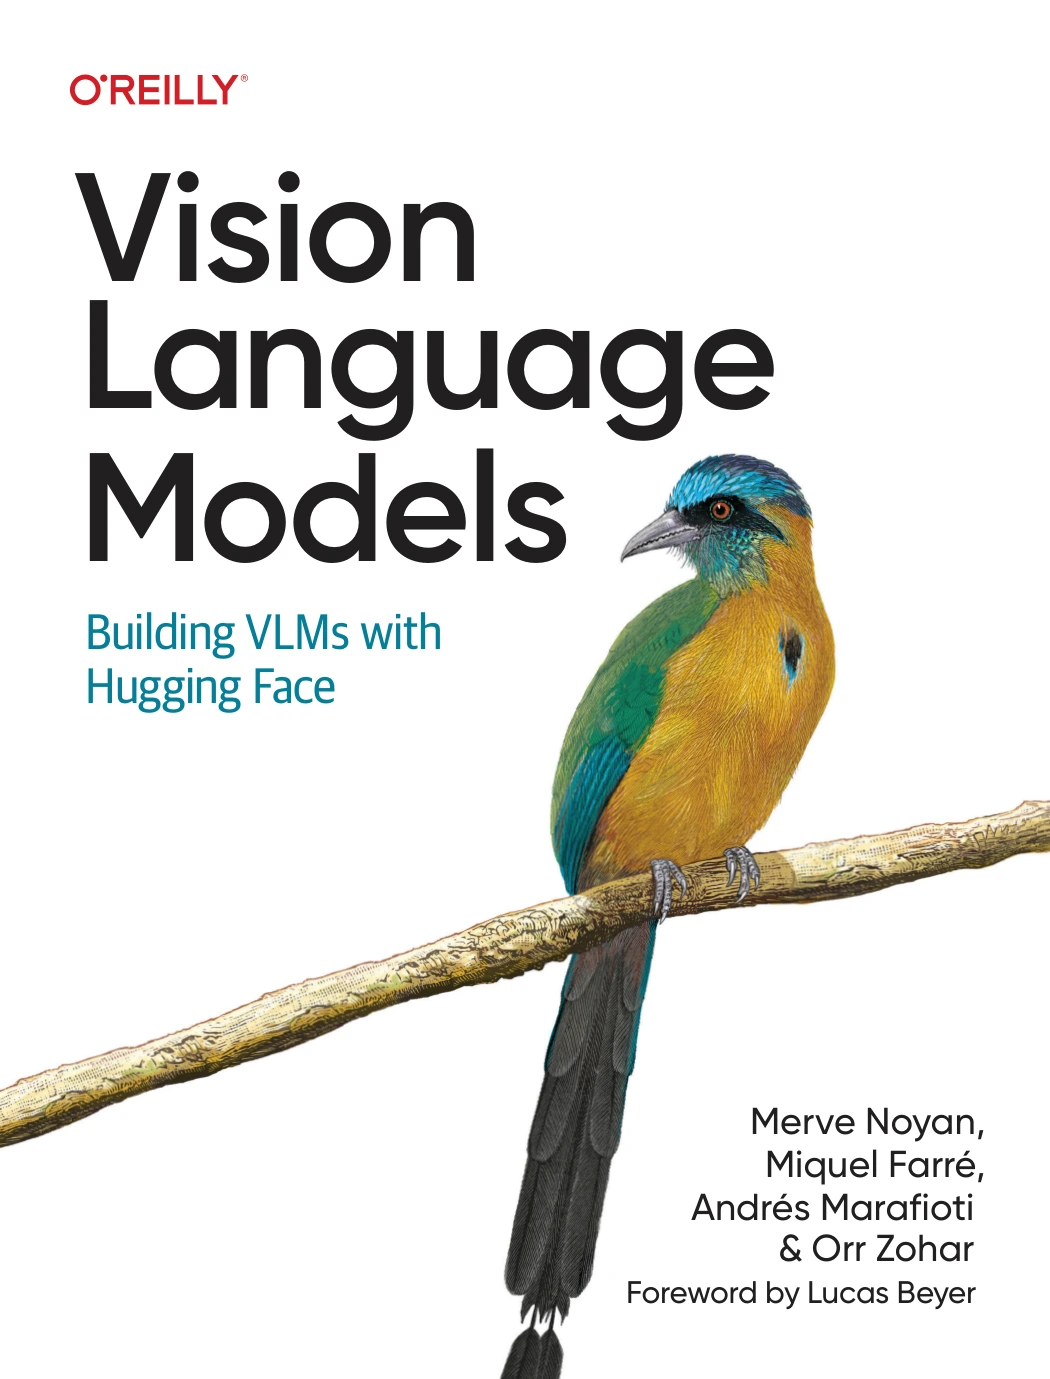
Vision Language Models: Building VLMs with Hugging Face
Original price was: $79.99.$39.99Current price is: $39.99.

Merve
Product Specs:
- File Type: PDF
- File Size: 31.2 MB
- Book Language: English
- Total Page Count: 409
- Instant Download
Build Real Vision Language Models with Confidence
Vision language models are changing how machines understand the world—connecting images, text, and video in ways that were hard to imagine just a few years ago. Vision Language Models: Building VLMs with Hugging Face is a hands-on engineering book that moves beyond theory and puts the latest multimodal techniques directly into your workflow.
Written by Merve Noyan, Miquel Farré, Andrés Marafioti, and Orr Zohar, this guide reflects the practical experience of researchers and engineers who have built VLM stacks at Hugging Face, Meta, NVIDIA, and beyond. The result is a book that feels like a mentor walking you through the entire pipeline—from data to deployment.
What You’ll Work With Inside
The book covers the full VLM lifecycle, with plenty of code examples and real-world context. You’ll learn how to:
- Explore core architectures—from multimodal attention and adapter-based fusion to unified sequence approaches.
- Prepare high-quality training data—for images, video, and vision-language-action tasks, including dataset sourcing and filtering at scale.
- Fine-tune and post-train models—using supervised fine-tuning, parameter-efficient methods, RLHF, DPO, and group relative policy optimization.
- Optimize inference—with KV cache, FlashAttention, quantization, and export formats like ONNX and TensorRT.
- Deploy to real environments—on GPU servers, browser with, mobile, and Apple Silicon with MLX.
Dedicated chapters also tackle document AI—information extraction, parsing, and retrieval—and video-language models, including temporal modeling, video retrieval, and fine-tuning for domain-specific tasks.
Why This Guide Stands Out
Rather than expecting you to read dozens of research papers, the authors have distilled the most important ideas into clear explanations and runnable code. The progression is practical: you’ll start with a simple VLM architecture, then gradually scale up to production-grade systems. Along the way, the book addresses the hidden challenges—dataset mixture design, memory constraints, quantization asymmetries, and edge deployment—that often trip up real projects.
Whether you’re an ML engineer looking to add vision-language capabilities to your product, a data scientist expanding into multimodal work, or a developer curious about the open-source VLM ecosystem, this book gives you a solid technical foundation without fluff.
A Practical Addition to Your AI Library
At Digital Delights, we value books that combine depth with immediate usefulness. Vision Language Models does exactly that. If you want to build systems that truly see and communicate, this is a reference you’ll return to again and again.
User Reviews
Only logged in customers who have purchased this product may leave a review.
Original price was: $79.99.$39.99Current price is: $39.99.
There are no reviews yet.