

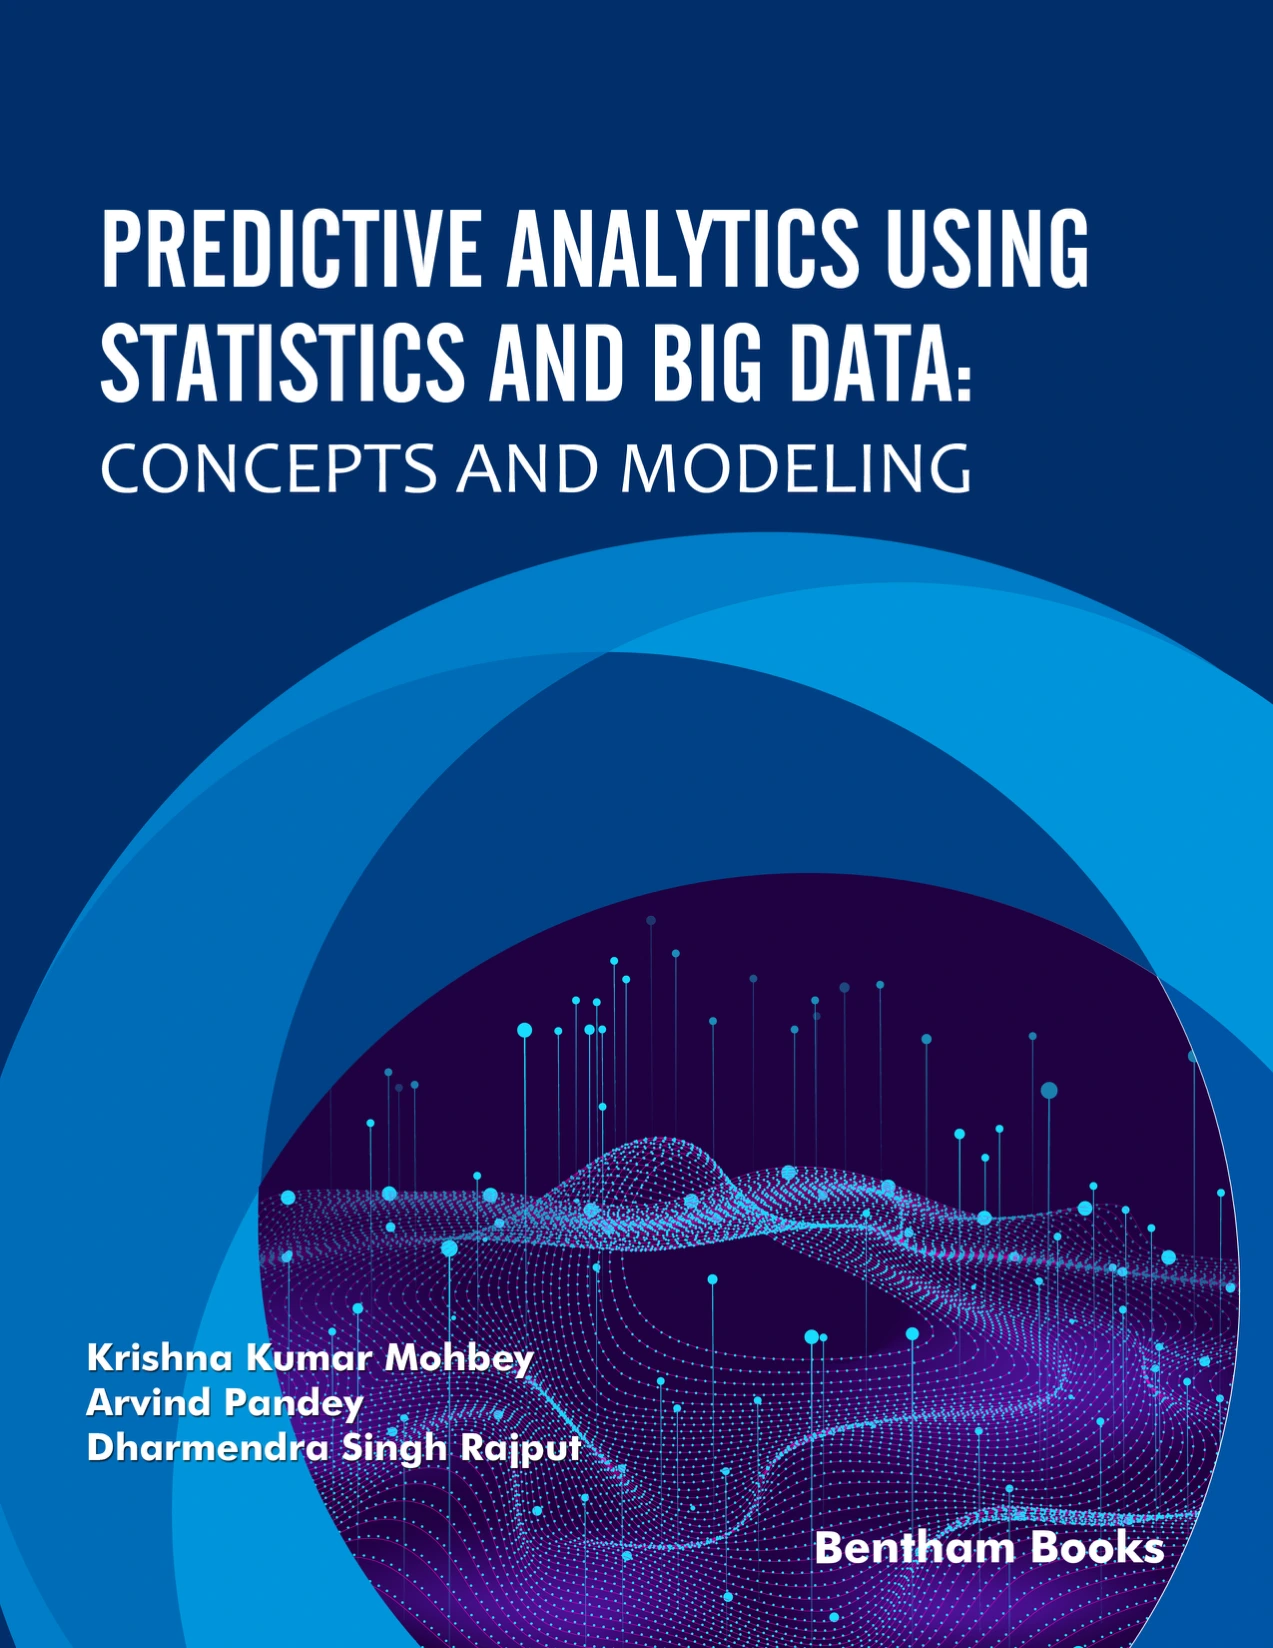
Predictive Analytics Using Statistics and Big Data: Concepts and Modeling
Original price was: $5.00.$2.50Current price is: $2.50.

Krishna Kumar Mohbey
Product Specs:
- File Type: PDF
- File Size: 12.7 MB
- Book Language: English
- Total Page Count: 124
- Instant Download
Where Statistical Thinking Meets Big Data Practice 📊
Predictive analytics rarely lives in a single discipline. It borrows from statistics, machine learning, data engineering, and domain knowledge. This edited volume, published by Bentham Science in 2020, brings those threads together across seven research chapters. The editors—Krishna Kumar Mohbey, Arvind Pandey, and Dharmendra Singh Rajput—have assembled work that ranges from broad machine-learning applications to focused estimators and applied case studies.
Seven Chapters, Several Ways of Thinking About Prediction
The book opens with data analytics across domains, using categorized machine-learning algorithms and regression examples drawn from medical, agricultural, and social data. From there, the chapters move into sampling theory and estimation: bootstrap sampling is applied to a cricket-team question, generalized chain-type estimators are examined under successive sampling, and log-type estimators of population mean are studied under ranked set sampling. A later chapter presents a Bayesian approach to bivariate survival data through shared inverse Gaussian frailty models, including an analysis of kidney infection data. The final chapters turn to weblog analysis with machine learning and an exploratory data analysis of COVID-19.
Methods and Concepts in the Volume 💻
- Supervised and unsupervised machine learning
- Logistic, linear, and multiple linear regression
- ANOVA
- Bootstrap sampling and successive sampling
- Ranked set sampling and chain-type estimators
- Bayesian survival analysis and frailty models
- Exploratory data analysis for epidemic data
- Big data technologies such as Hadoop, Hive, HBase, and Spark, as discussed in the preface
From Theory to Applied Data Cases 📈
The chapters do not treat statistical modeling as an isolated exercise. They connect methods to data problems: estimating population characteristics, modeling survival times, analyzing web logs, and making sense of COVID-19 data. That applied orientation is one of the book’s strengths. Readers can see how different techniques are chosen, adapted, and interpreted when the data are complex or incomplete.
Who Might Use This Book
This is an edited research volume, so it is likely to suit researchers, postgraduate students, and practitioners in statistics, data science, machine learning, and applied analytics. It may also be useful for readers who want a chapter-based overview of predictive analytics rather than a single-author textbook. The material assumes some familiarity with statistical concepts and data analysis; it is not an introductory programming guide.
A Compact Research Reference
Because each chapter is written by a different author team, the volume offers a range of perspectives and methodological priorities. That variety makes it a useful reference for exploring how predictive analytics is being applied across sampling theory, survival analysis, machine learning, and epidemic data analysis. For readers building a technical library, this ebook provides a focused look at the statistical and big data foundations behind predictive work.
User Reviews
Only logged in customers who have purchased this product may leave a review.
Original price was: $5.00.$2.50Current price is: $2.50.
There are no reviews yet.